
Our research spans mathematics, computer science, and their applications, with a particular focus on their intersections. We develop efficient, reproducible pipelines for large, complex datasets and seek a deeper mathematical understanding of the concepts and methods underpinning modern data science and artificial intelligence.
Explore a selection of our research topics below.
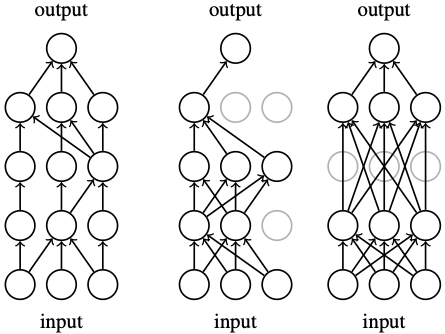 |
Deep LearningDeep learning builds predictive models inspired by the brain’s neural networks and has become one of the most active areas of research. We advance the field by developing new concepts and rigorous theoretical foundations. Our interdisciplinary approach connects statistics and optimization with challenges arising from real-world applications. |
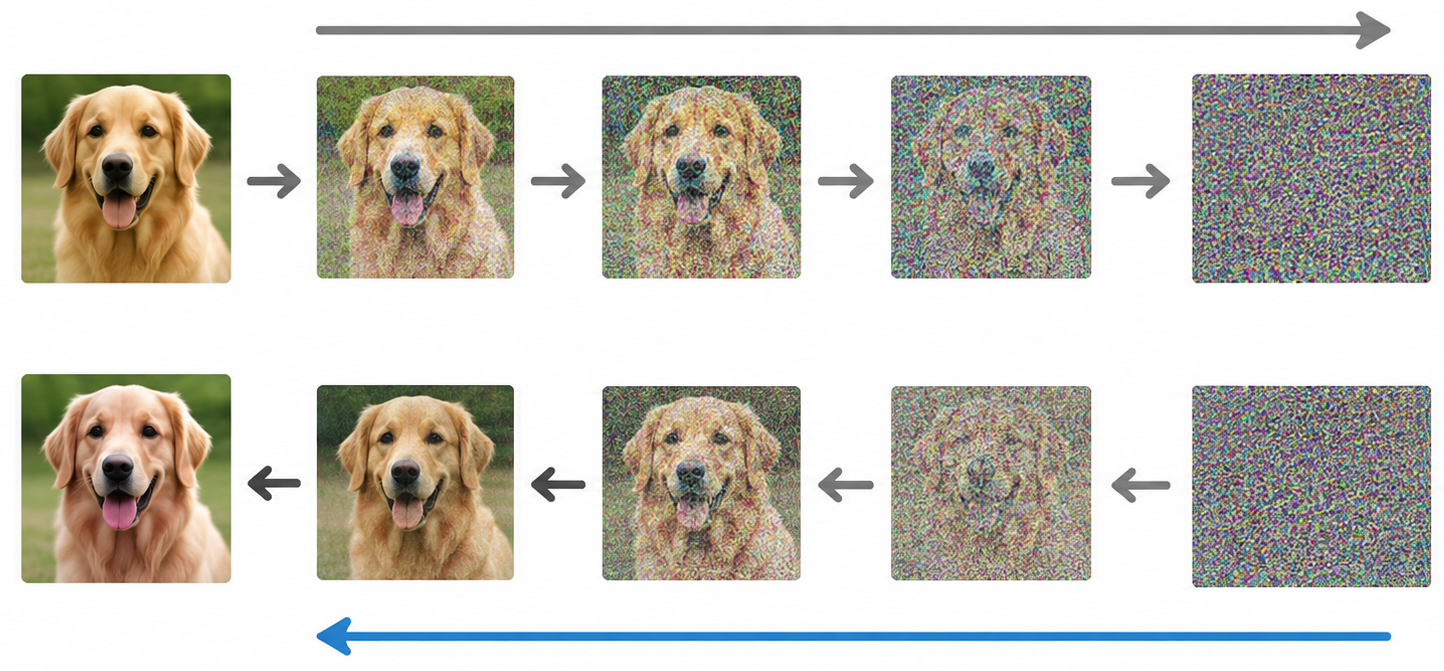 |
Diffusion ModelsDiffusion models generate new data by learning to reverse a process that gradually adds noise to training examples. Starting from random noise, they build structure step by step, enabling applications ranging from image and video generation to speech synthesis and molecular design. Their ability to generate complex, realistic outputs makes them an important tool for both creative applications and scientific discovery. Our research develops new concepts and rigorous theories to understand and improve these models. |
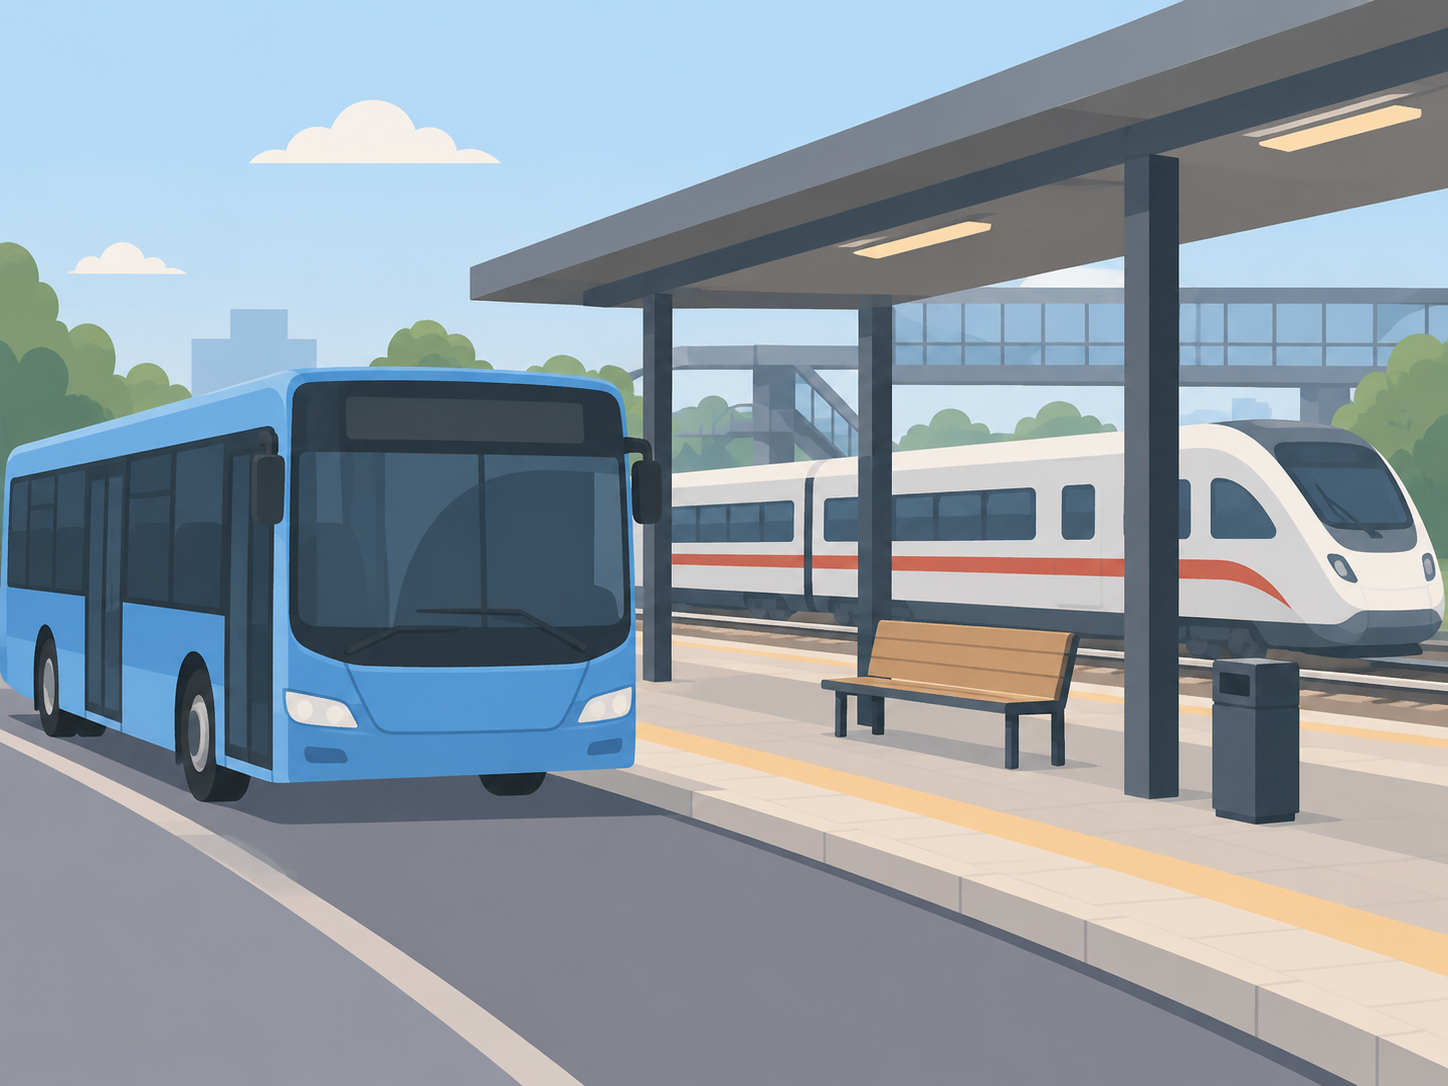 |
Data-Driven MobilityData-driven mobility combines data, statistics, and artificial intelligence to understand and improve how people and goods move. Drawing on information from vehicles, infrastructure, and travelers, it helps anticipate demand, coordinate transport services, and support autonomous systems. A central focus of our research is a counterintuitive phenomenon: certain forms of unreliability can enhance, rather than undermine, user experience. |
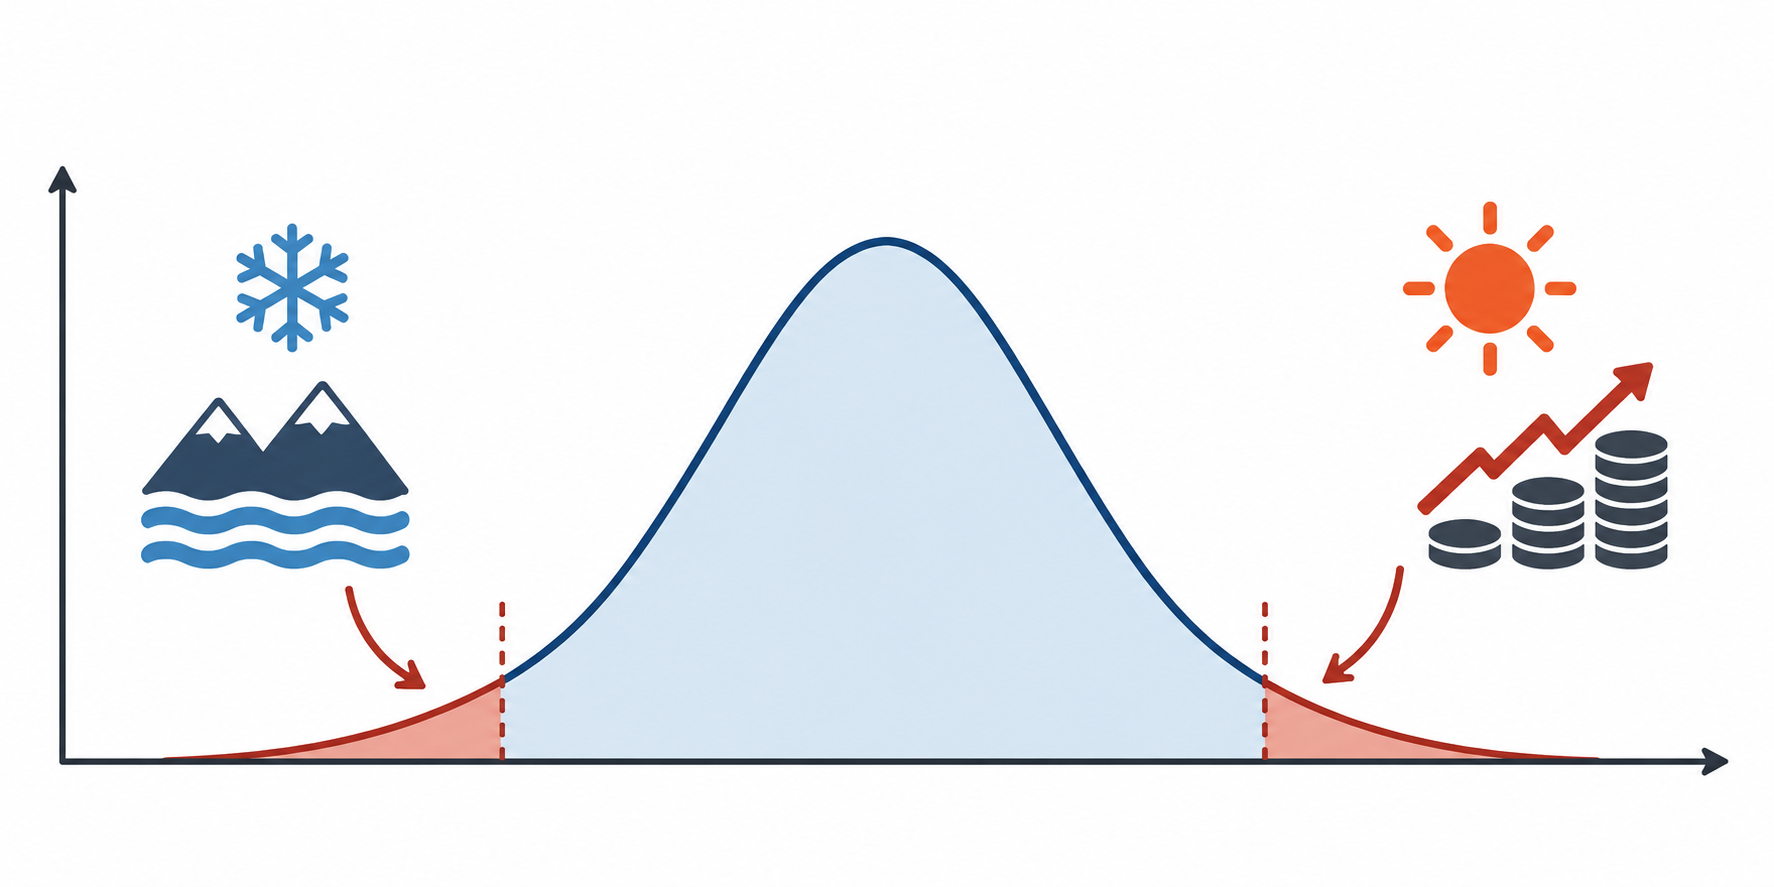 |
Extreme ValuesExtreme-value theory provides a mathematical framework for understanding rare events and exceptionally large or small outcomes. Rather than describing typical behavior, it explores the tails of probability distributions, where data are scarce and uncertainty is high. Our research focuses on developing scalable statistical methods and computational algorithms for multivariate extremes. |
 |
High-Dimensional StatisticsThe number of observed parameters in contemporary data sets is often much larger than the number of samples. To obtain good estimates in such settings, all information about the data needs to be incorporated, and the methods need to be carefully calibrated. We develop corresponding statistical tools and equip them with mathematical theory. For example, we establish calibration schemes that satisfy rigorous mathematical bounds. |
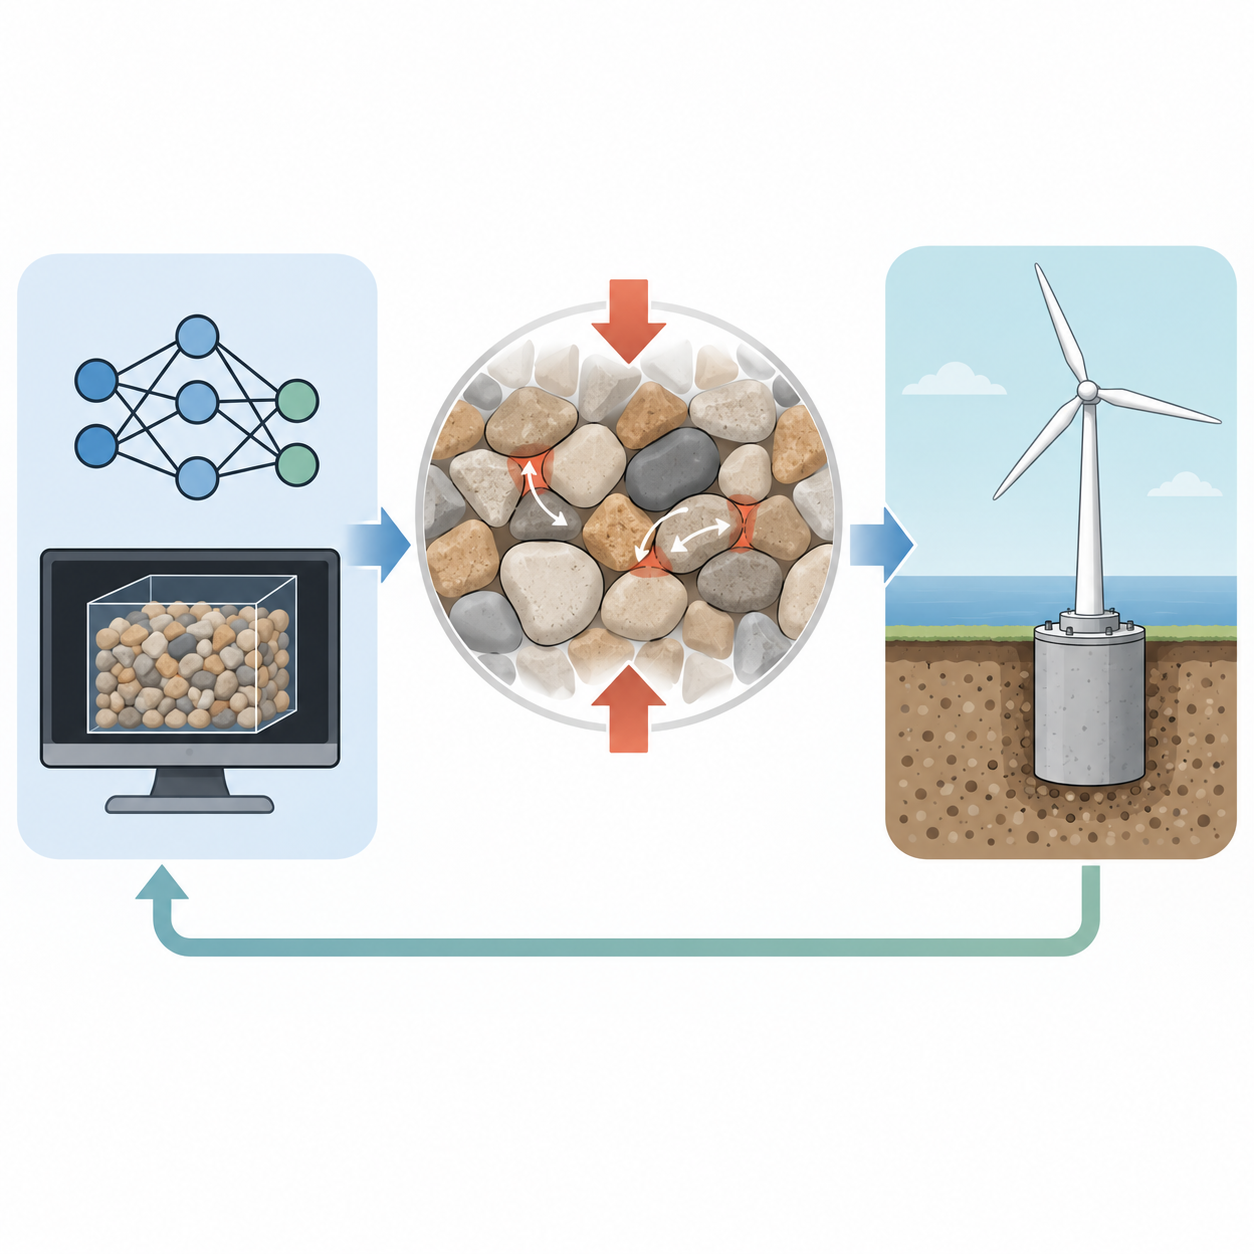 |
Civil EngineeringWe combine artificial intelligence with detailed computer simulations to understand how sand and other grain-based materials respond to forces. We are particularly interested in how the shape and arrangement of individual grains affect deformation and develop methods to predict how contacts between grains change under stress. In this way, we aim to make soil modeling more efficient and support better-informed engineering decisions, such as the design of wind-turbine foundations. |
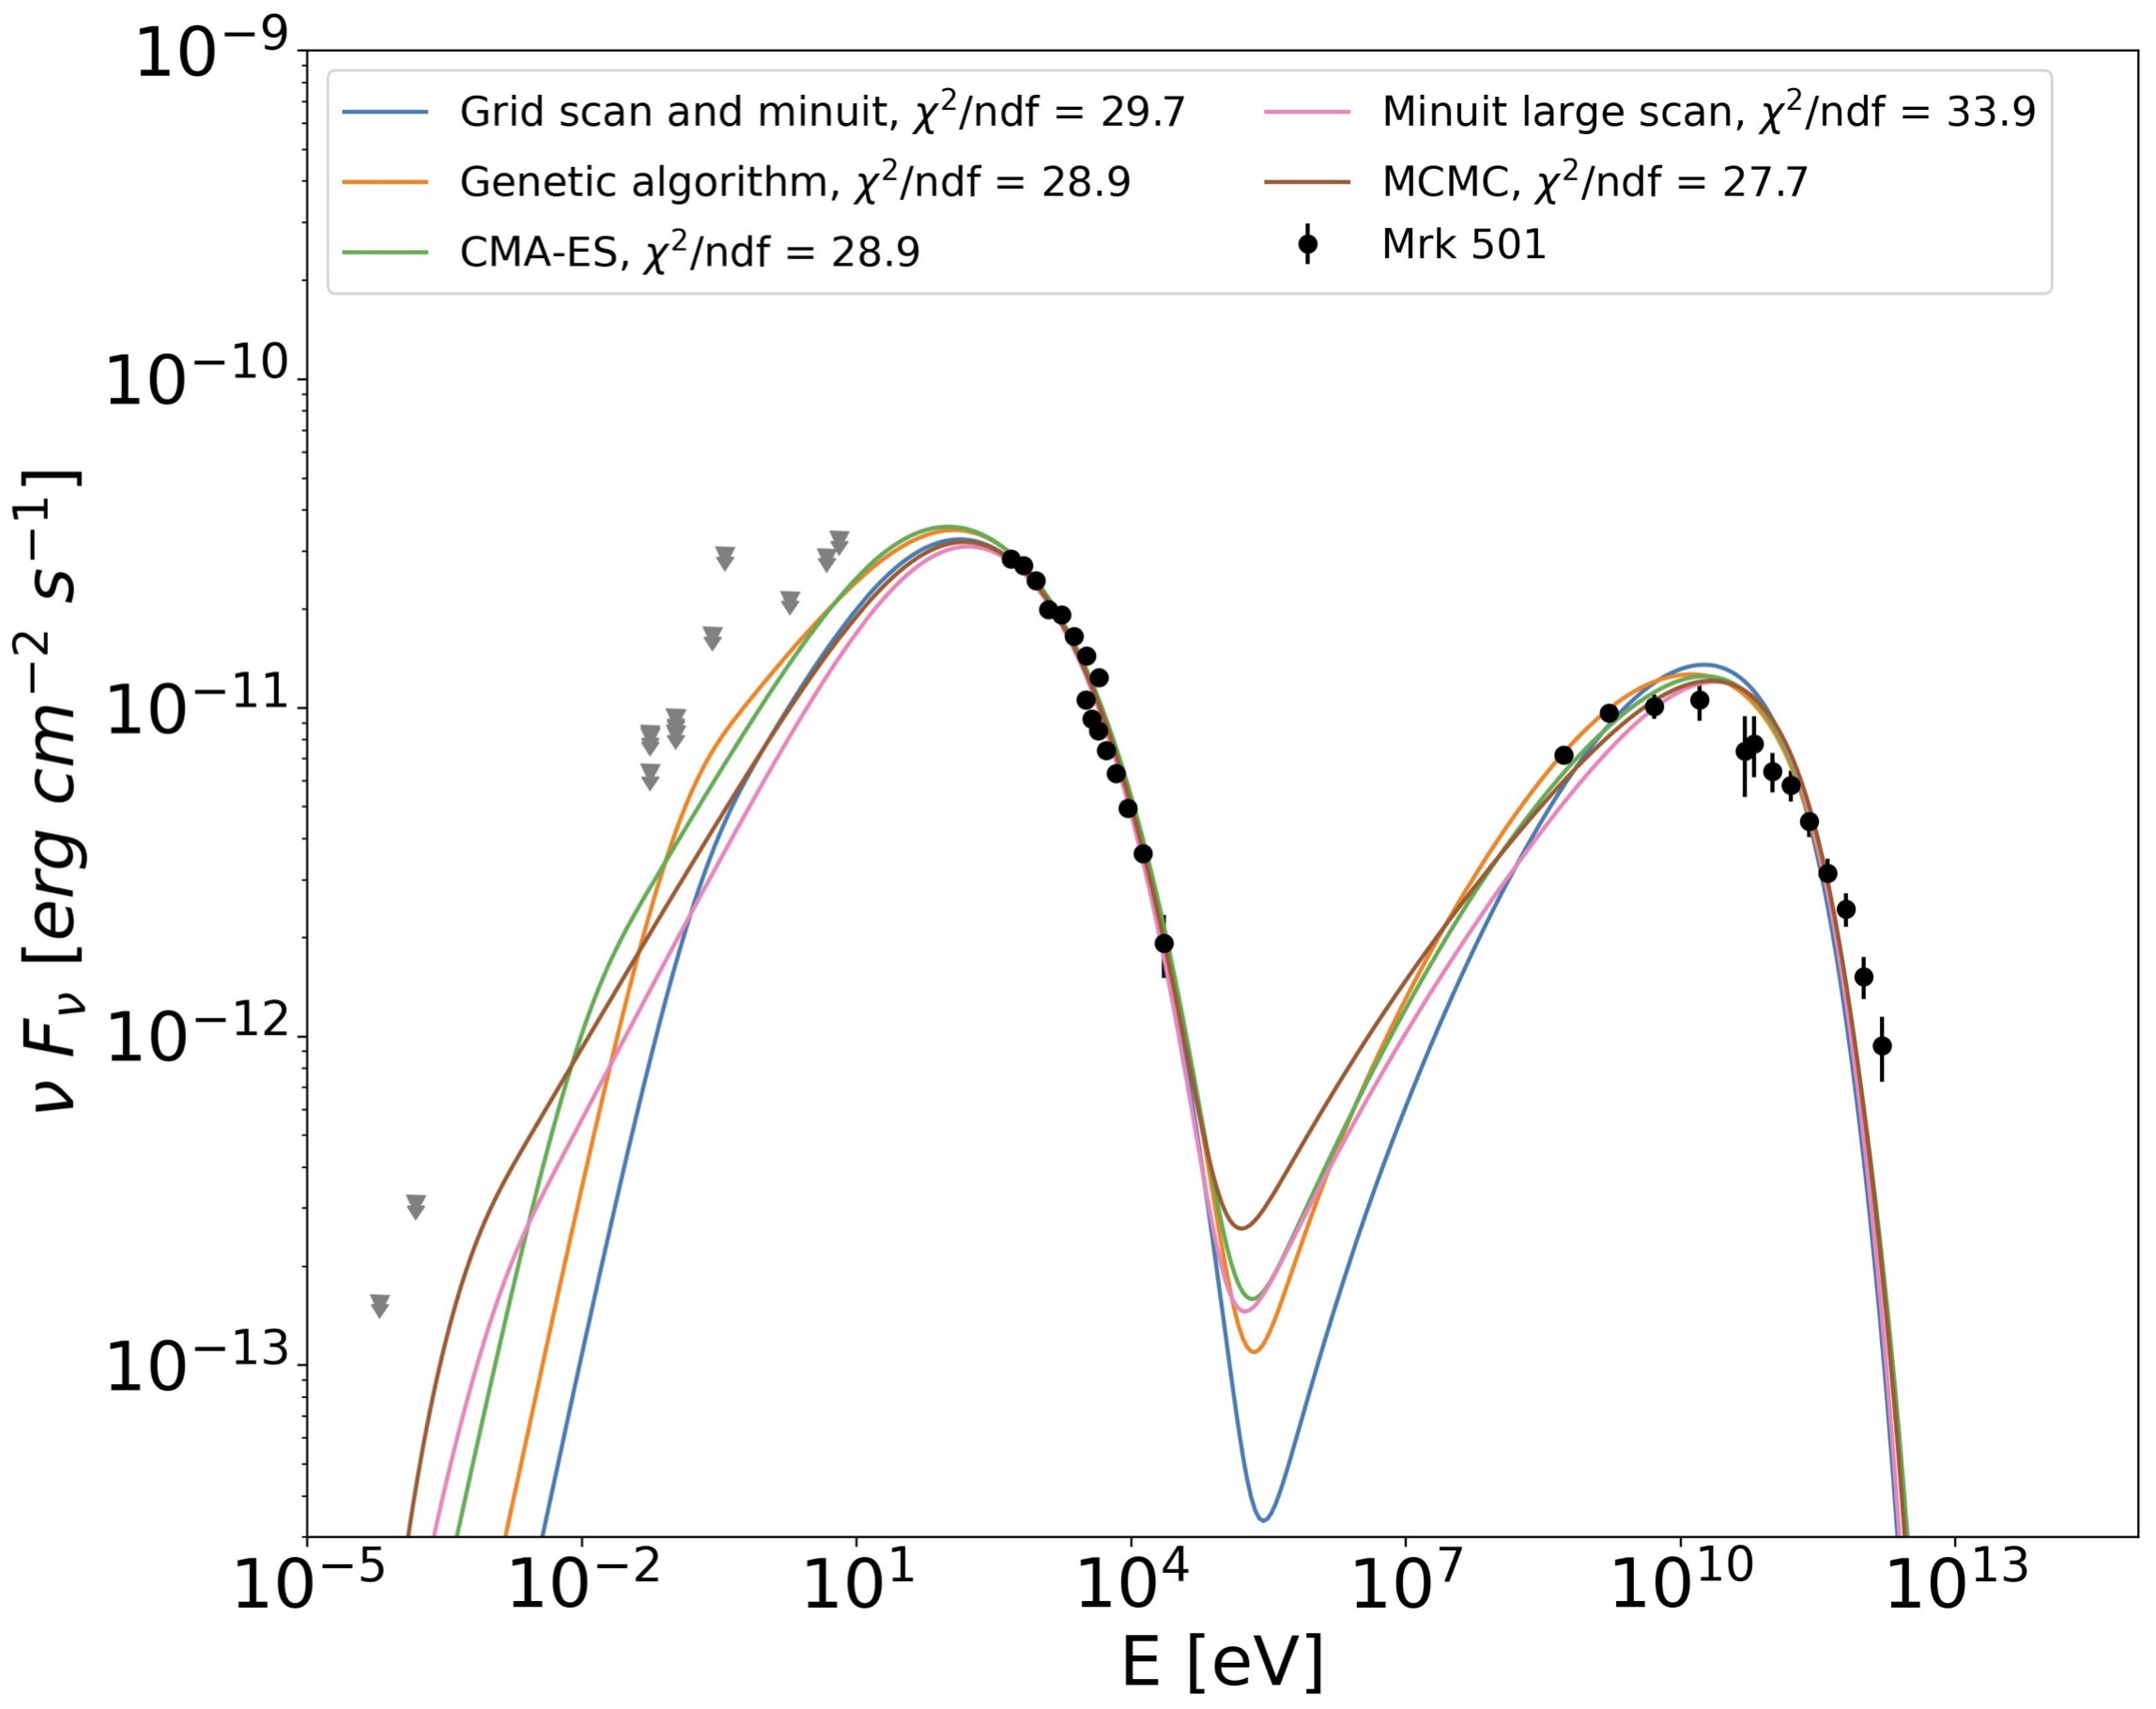 |
Machine Learning in PhysicsMachine learning helps physicists uncover patterns in complex data and understand the underlying physical processes. By linking observations with computer simulations, it enables us to estimate properties that are difficult to measure directly. For example, we investigate how reliably light from blazars—active galactic centers with powerful jets pointing toward Earth—can reveal the physical conditions within those jets. |
 |
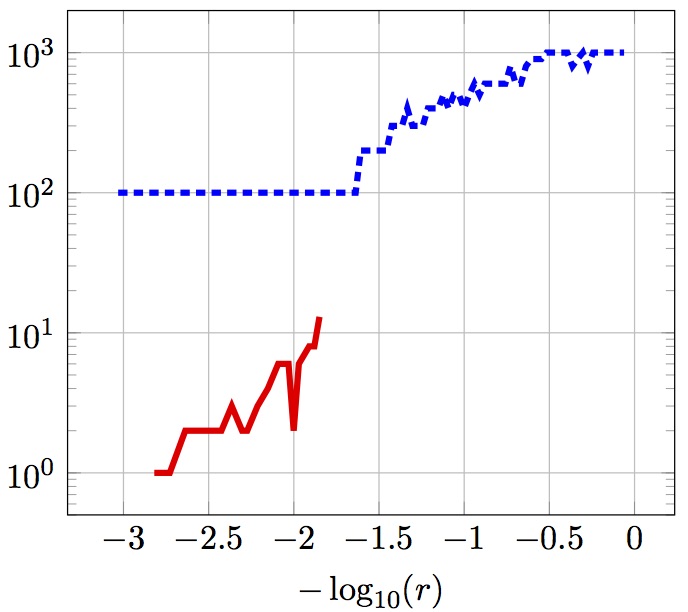
Biological NetworksNetwork models describe connections among entities in a system. Such models are used across many scientific disciplines, including economy, sociology, biology, medicine, and physics. We develop general frameworks for network models and investigate their properties in applications. We primarily focus on networks in biology and medicine, such as brain-connectivity networks and gene-regulation networks. |
 |
Big DataThe advent of high-throughput technologies allows one to collect data at unprecedented frequencies. This leads to enormous data sets that are too large for traditional analysis techniques. We develop algorithms and software that can address these new challenges providing fast analyses even of data with many millions of samples. |
 |
Empirical ProcessesEmpirical processes are mathematical objects that are ubiquitous in statistical theories. We are especially interested in concentration bounds for empirical processes. Classical examples are Bernstein’s and Höffding’s inequalities. In our research, we develop new bounds that relax the assumptions on the underlying model. These bounds serve as a theoretical basis for evaluating statistical methods, both in classical as well as high-dimensional settings. |
 Johannes Lederer
